
Python in Jupyter Notebooks for data analysis
About Python
Python is a near to plain-English programming language, popular in education. It is widely used for data analysis work, but can also be used to program microcontrollers and web applications (using the Django framework). That ubiquity and portability means it is good to learn. Code and code libraries used in one platform (for example Jupyter notebooks) may usually be used in often very different platforms (e.g. Django web applications). There is another similar language used for data analysis, called R. But that is much less portable. So we have decided to focus on Python. There are a lot of people around who know the language - people you can get help from or even work with.
The one key thing about Python that programmers from other language families get upset about is the way in which it encapsulates related lines of code. I'm from the C, C++, Java, and Javascript world. We use { curly brackets } to enclose lines. So for example, in Javascript code we might write this (see how we can also add non-code comments using // which are ignored when the code runs):
function helloWorld() //start of the function
{
    console.log("Hello sailor!"); //this is the code that runs when we call the helloWorld function
} //end of the function
//outside of the function
In Python the indenting of the lines of code tells the interpreter (what turns the code into instructions) related code starts and ends. For a Javascript programmer, this is madness. But the systems in which we write Python usually use subtle lines so we can see the indenting better. Here's an example. Python uses # for comments.
def helloWorld(): #this the start of the function
   #this is inside the function
   print("Hello sailor!")
#this is outside
Also notice how most lines of code in Javascript end in a semi colon ; but no such system is used in Python. Weird, but actually effective.
If you want to know more about Python, use the W3SchoolsLink opens in a new window tutorials and documentation. You will also pick it up by looking at our examples and tinkering.
Jupyter Notebooks
For an old-fashioned application developer like me, the way in which Jupyter Notebooks works is absolutely mindblowingly weird. For ordinary people it is entirely rational and obvious!
It uses what we call a REPL approach, embedded into an ordinary plain English document (in fact we can add style, links, images etc. to the text as well using HTML). We write some text (say introducing our research question), then add some Python code (for example, to import data). We run the code, and the results appear beneath it. We can then add more text to provide commentary. And another block of Python code to work on the data. Repeat until complete! REPL stands for Read Evaluate Print Loop - each block of code is read, evaluated, the result printed, and then we do more processing on the output, with commentary added in between. We build this up iteratively - a pattern that fits well with how people actually do research.
Most importantly for us tinkerers, we can easily change the code and the commentary to evolve our research creatively. We don't even need to plan much how we are going to proceed through the investigation, just tinker, reflect, tinker, reflect. Doing this, we can produce shareable research documents (notebooks) that show our working out. Using a platform like GitHub (designed for sharing open source code) we can let others make copies of our work and develop it for their own use. They can even then merge their versions back with us.
Example - Titanic survivors
You can look at the complete notebook for this example online.Link opens in a new window
You know the famous rule of the oceans? The Birkenhead protocol? Women and children first! But did they really do that on the Titanic? And how did social class impact survival for men and women? Did all of the poor people drown in the icy seas and the rich people survive in the lovely warm lifeboats? We have the data. Python in Jupyter notebooks gives us the tools. This example is developed from the very good tutorial provided by Microsoft. You can follow that tutorial yourselves (you'll also need some info on how to get set up with Jupyter, given below). Our code for this version is available publicly on the DAHL GitHub repoLink opens in a new window (that's short for repository, place for storing code).
Here's some highlights to illustrate how the example works. The notebook itself contains a full explanation of all of the steps and the code.
First we import the data. It is in the same comma-separated variable (CSV) format that Excel is able to export and import.
data = pd.read_csv('titanic3.csv')
That makes a dataframe that we can query and manipulate. Each row in the frame is structured in the same way, with each column having a title (e.g. name). Next we can query the data. In this case, we make another dataframe just containing people who's fare was more than £200 - so the wealthier people.
wealthy = data.query('fare > 200')
We could print that out into the notebook, or just show a sample. Jupyter also provides a simple tool for browsing through datasets. So in this case I used that to find an interesting passenger.
passenger49 = data.query('index == 49')

name = passenger49['name']

print(name)
I used his index number to get more details about him, and printed his name out into the notebook.
Cardeza, Mr. Thomas Drake Martinez
I then queried for other people travelling on that ticket (ticketing worked differently in the past, the main passenger, usually the head of the household, had the ticket).
ticket = passenger49.ticket

ticketId = ticket.values[0]

qstring = "ticket == '" + ticketId + "'"

print(data.query(qstring))
From that I could see that he was in a party of four, an older woman with the same name (turned out to be his mother) and two people who, I guessed from the fact they didn't have address data, were servants. I then turned to the web to learn about these specific people in detail, and added what I learned into the notebook. I was also able to query for their suite of cabins, and online found full info on what turned out to be the most luxurious accommodation on the ship. The info online also told me how they managed to survive, plus an intriguing story of what the maid took with her - a fur coat and some valuables! Was she saving them or stealing them?
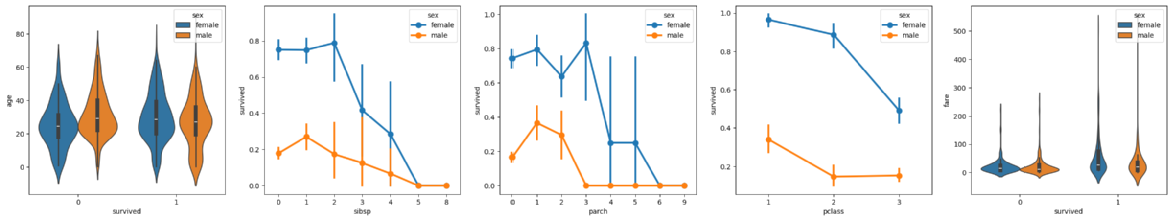
For the second part of the example, I zoomed out to the big picture. I created some charts and stats to explore if higher class men stood a better chance of survival than lower class women. Guess what, they did. The Birkenhead rule clearly was applied, but with social class also making a difference.
Here's the charts and the stats.
The numbers on the right of this table represent how statistically related the property on the left is to survival. 1 = 100% correlation.
| survived | |
|---|---|
| pclass | 0.312469 |
| survived | 1.000000 |
| sex | 0.528693 |
| age | 0.055512 |
| sibsp | 0.027825 |
| parch | 0.082660 |
| fare | 0.244265 |
The charts were made using this code:
fig, axs = plt.subplots(ncols=5, figsize=(30,5))

sns.violinplot(x="survived", y="age", hue="sex", data=data, ax=axs[0])

sns.pointplot(x="sibsp", y="survived", hue="sex", data=data, ax=axs[1])

sns.pointplot(x="parch", y="survived", hue="sex", data=data, ax=axs[2])

sns.pointplot(x="pclass", y="survived", hue="sex", data=data, ax=axs[3])

sns.violinplot(x="survived", y="fare", hue="sex", data=data, ax=axs[4])
And the stats using this:
data.corr(numeric_only=True).abs()[["survived"]]
Resources
Get a GitHub accountLink opens in a new window
Instructions for using Jupyter Notebooks in GitHub CodespacesLink opens in a new window
Python cheat sheetLink opens in a new window
Pandas cheat cheetLink opens in a new window
Titanic Jupyter Notebook example files referred to in this article (GitHub code)
Browse through the complete notebookLink opens in a new window
Full tutorial from Microsoft (Titanic data, with AI as well)Link opens in a new window
This course
Python in Jupyter Notebooks for data analysis